Articles tagged "llm" - Page 2
Tag: llm
10-Jun-2026
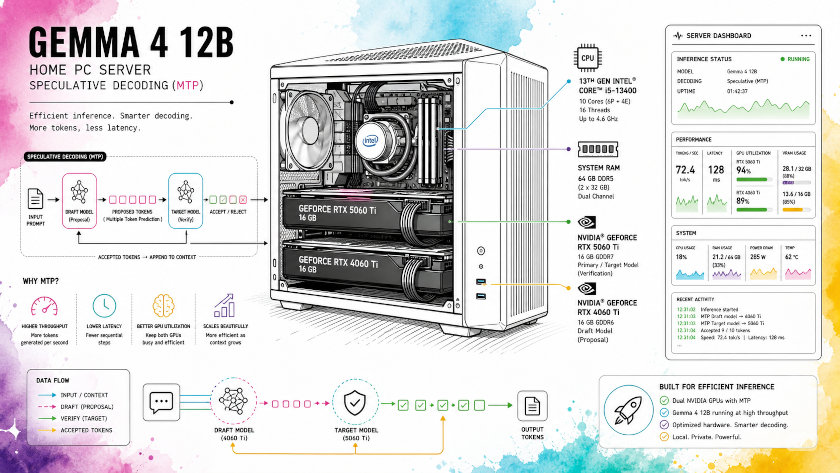
Running Gemma 4 12B Locally with Speculative Decoding on Ubuntu
A practical guide to running Gemma 4 12B locally on Ubuntu using llama.cpp, Hugging Face automatic model loading, and speculative decoding with MTP.
15-May-2026
Running Gemma 4 31B Faster at Home with Speculative Decoding
A practical guide to running Gemma 4 31B on a dual-GPU Ubuntu box using llama.cpp TurboQuant, Gemma 4’s MTP assistant head, and speculative decoding to nearly
24-Jan-2026
Running Large Language Models Locally: Complete Hardware Guide for GLM-4.7 Deployment
Comprehensive guide comparing hardware platforms for local GLM-4.7 (358B MoE) inference, from budget single-GPU setups to production-grade clusters with real
20-Nov-2025
Local AI on RTX 4060 Ti: Setup & Performance Guide
Complete guide to running local AI models (7B-30B) on RTX 4060 Ti with context optimization from 4K to 15K tokens, real benchmarks, and SGR examples.
Loading tags...