Articles tagged "llm"
Tag: llm
12-Sept-2026
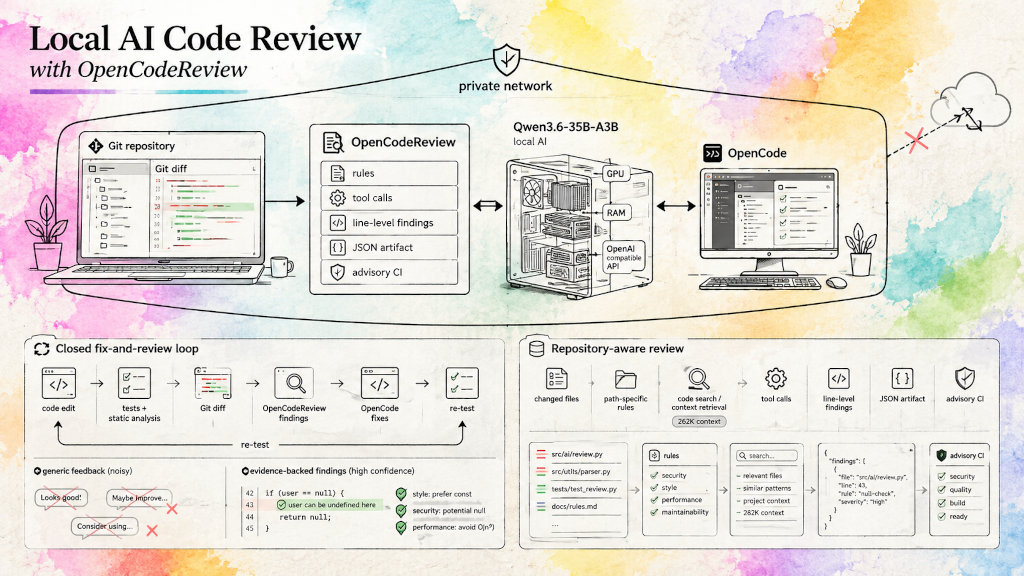
Local AI Code Review with OpenCodeReview, OpenCode, and Qwen3.6-35B-A3B
A practical, local-first workflow for running deterministic AI code reviews through OpenCodeReview against an OpenAI-compatible Qwen3.6-35B-A3B endpoint.
09-Sept-2026
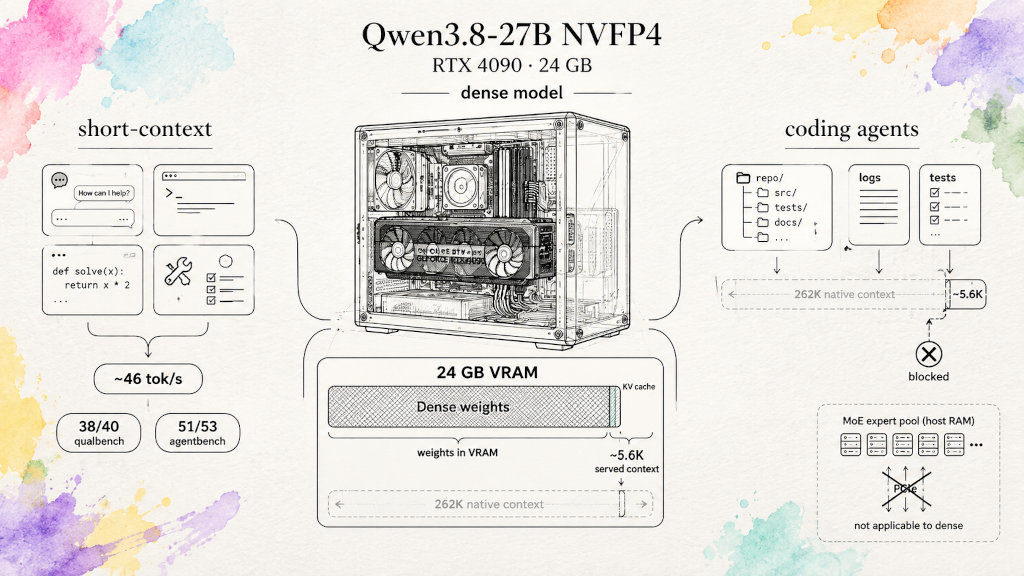
Qwen3.8-27B-NVFP4 on a 24GB RTX 4090: What a Dense Model Can and Cannot Do
Qwen3.8-27B-NVFP4 on RTX 4090 with FreeToken: dense weights fit, but the KV ceiling is ~5.6K tokens — 38/40 qualbench, 51/53 agentbench.
03-Sept-2026
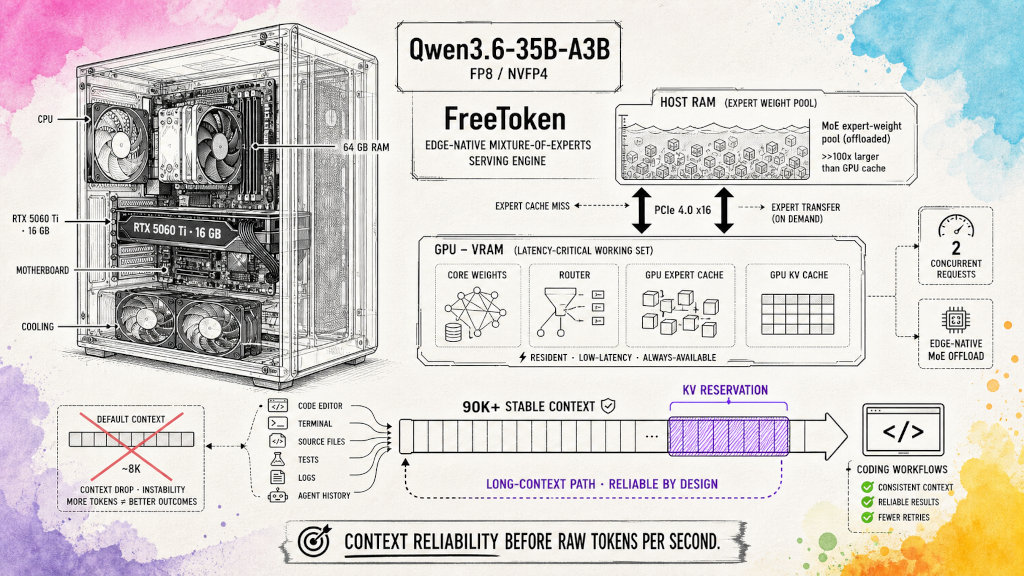
Qwen3.6-35B-A3B on a 16 GB RTX 5060 Ti: Why Context Beats Tok/s for Coding
Qwen3.6-35B-A3B on a 16 GB RTX 5060 Ti with FreeToken: long-context tuning, FP8 vs NVFP4 throughput and correctness, and real memory requirements.
29-Aug-2026
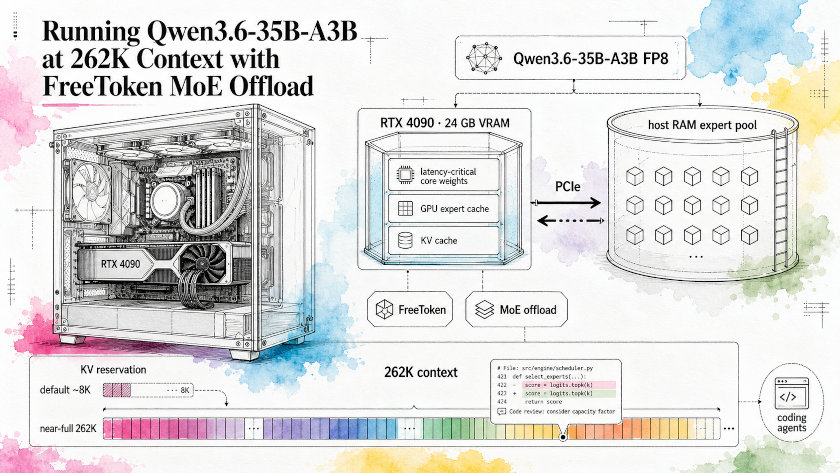
Running Qwen3.6-35B-A3B at 262K Context with FreeToken MoE Offload
Qwen3.6-35B-A3B-FP8 on RTX 4090 with FreeToken: near-262K context verification, 51/51 statistical rerun, a 50-task correctness eval (46/50) with explicit truncation detection, and a systemd autostart setup.
Loading tags...