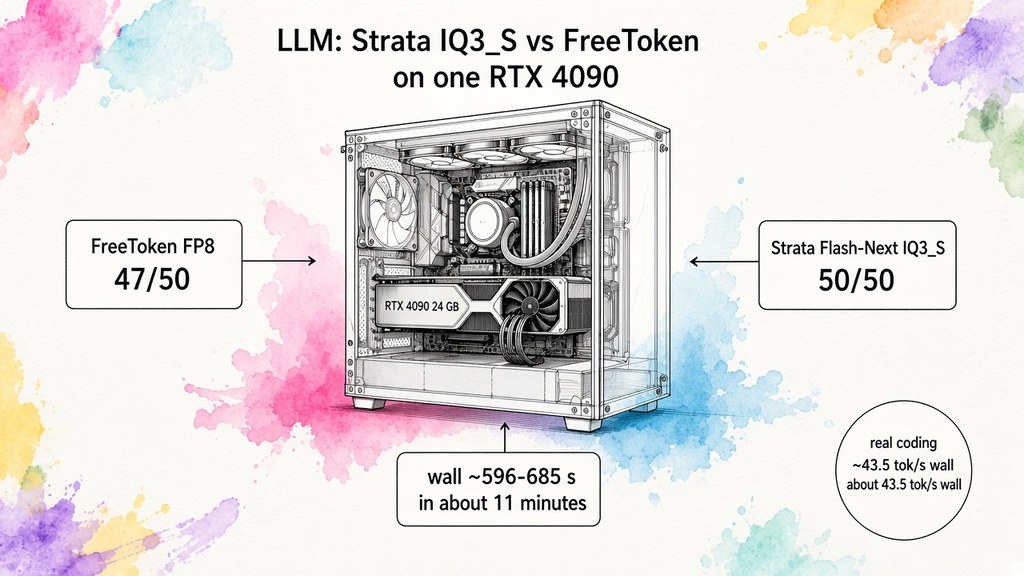
Strata IQ3_S vs FreeToken on an RTX 4090: Qualbench Score and Speed
This site already had a FreeToken + Qwen3.6-35B-A3B-FP8 stack on a 24 GB RTX 4090, and a separate article on what a dense Qwen3.8-27B-NVFP4 can (and cannot) do on that card. The next question was narrower than "which model is better": on the same host, how does a Strata deployment of Qwen3.8-Flash-Next IQ3_S compare to the working FreeToken baseline on the same text correctness suite, and does adding the RTX 5060 Ti via Strata layer-split help?
Update (2026-10-15, after the benches): Bifrost provider llm-88 was cut
over to Strata IQ3_S on 1×4090 (:8080). Served / Bifrost model id was
llm-88/qwen3.8-flash-next-iq3_s (compat alias qwen3.6-35b-a3b retired).
FreeToken :8000 is disabled; the 5060 Ti stays on ASR/embeddings. A
post-reboot prod re-check of text qualbench-50 scored 50/50 in 685 s.
Update (2026-10-17): cutover IQ3_S → Unsloth UD-Q4_K_XL. Same Strata
engine and port :8080, new pack (iq_pack --compat-bf16), served id
qwen3.8-flash-next-ud-q4_k_xl. Full resident experts (no
--resident-budget). Same text suite: 48/50 (sql 4/6 with Postgres up;
non-sql categories still perfect). Context matrix A-E and calibrated F
(~248K needle) all PASS. Cost vs IQ3_S on this host: host RAM ~88 GiB
vs ~62 GiB, long-prompt prefill ~1.25k vs ~2.0k tok/s. IQ3_S
restore snapshot kept on disk for rollback.
Update (2026-10-18): UD-IQ4_XS A/B, then restore IQ3_S. Same suite
48/50 (sql 4/6 again), better RAM/prefill than UD-Q4_K_XL but still
behind IQ3_S on score and long prefill. Prod returned to
qwen3.8-flash-next-iq3_s.
Update (2026-10-28): Strata engine → v0.2.7.1 / 0.1.53. IQ3_S profile
unchanged. Qualbench 50/50 @ 639 s; matrix A-E + F-calib PASS;
Monitor decode/prefill gates PASS. Known agentbench contract fails
unchanged (meta.n_ctx, count_tokens 401, etc.).
Update (2026-10-30): Maya GLM-5.3-Flash side experiment. Same host,
Strata stopped for the window, Project Maya Maya-S24 on :8090
(glm-5.3-flash, hard 32K). Full suite: Monitor OK, agentbench ~49
pass, matrix A/B + calibrated ~31K OK, qualbench 41/50 @ 596 s
(7 fails = 64K/150K rejects; 2 quality fails). Decode ~27-45 t/s,
about 4-6× slower than Strata Flash-Next on short turns. Strata
IQ3_S restored on :8080 after the run. Detail:
/ai/maya-glm53-flash-rtx-4090-qualbench.
Update (2026-10-30, evening): Strata IQ3_S full-suite recheck after the Maya window. Same engine v0.2.7.1. Qualbench 50/50 @ 644 s; Monitor warm ~26K prefill 1769 / decode 119; matrix A-E + F-calib (~248K needles 3/3) PASS; raw F@262K still HTTP 400. agentbench fast 49/6, slow 55/5 (known contract fails only). Prod IQ3_S did not regress after Maya stop/start.
Update (2026-10-31): gpu-unlock on the 4090 (Ada experimental). Same IQ3_S
stack (gpu-unlock 2.0.0, target PCI 0000:01:00.0 only). Unlock journal
PASS (SS0=0x88888888). Monitor/matrix prefill ~0-1% vs locked; decode
flat; unlocked qualbench 48/50 @ 645 s vs locked recheck 50/50 @
644 s (score flake, not speed). Rolled back via GRUB cmdline (packages
left installed, inert without targets=). Matches the upstream quantized /
memory-bound expectation: not useful for this MoE IQ3_S path.
Update (2026-11-06): Strata engine → v0.2.11 / 0.1.57. IQ3_S profile unchanged. Qualbench 49/50 @ 586 s (sql flake; retry 6/6); matrix A-E + F-calib PASS with long prefill clearly up (~3.8-4.6k on C/E vs ~1.9-2.1k on 0.2.7.1). Monitor decode gates PASS. gpu-unlock still off.
Update (2026-11-06, evening): "parallel": 2 on prod IQ3_S. Config
top-level field (maps to engine --batch 2; do not put --parallel in
args, Qwen rejects it). After reboot: dual-chat OK, agentbench concurrency
3/3, qualbench 50/50 @ 596 s, matrix A-E + F-calib PASS. Free VRAM
~0.5 GiB (engine warns about paging); solo decode probe a bit softer
(~87 t/s). Useful for two light clients, not a free single-user speedup.
Update (2026-11-07): temporary Gemma-4 31B QAT cutover on :8080. Strata
unit masked; vLLM 0.25.1 serves google/gemma-4-31B-it-qat-w4a16-ct
(~23.3 GB W4A16) on GPU0 only (max-model-len=3072, util 0.98, tool-parser
gemma4). Alias qwen3.8-flash-next-iq3_s kept for Bifrost. Qualbench
runnable 37/40 (~37/50 if long-ctx count as unavailable); agentbench
fast 44/10; decode ~41 t/s; prefill ~2k. GPU1 ASR/embeddings
untouched. ~3K is not efficient for real agent work: practical minimum
32K, preferred 128K; this fit is smoke/paper only. Detail:
/ai/gemma-4-31b-qat-rtx-4090-qualbench.
Update (2026-11-07, evening): switch to Gemma-4 12B QAT on :8080.
Allowed competition variant google/gemma-4-12B-it-qat-w4a16-ct (~10.3 GB);
gemma4-12b-qat.service enabled, 31B unit disabled.
max-model-len=131072. Qualbench 42/50 @ 461 s (long-context
7/10); agentbench fast 46/8; decode ~51 t/s; prefill ~5-6.5k;
coding-wall proxy (gen-heavy, same output/Σdur formula) ~46 tok/s vs this
article's Strata UI ~43.5. Meets the ≥32K / ~128K bar the 31B fit could
not. Vs Strata IQ3_S: score 42 vs 50, peak decode ~2-3× slower,
coding wall ~tied when both are prefill-taxed, context 128K vs ~248K.
Usable as a competition stack, not a prod replacement. Detail:
/ai/gemma-4-12b-qat-rtx-4090-qualbench.
Restore Strata: unmask bak, disable Gemma unit(s).
The comparison is not apples-to-apples:
- Different model families (Qwen3.6-35B-A3B-FP8 vs Qwen3.8-Flash-Next IQ3_S).
- Different engines (FreeToken 0.1.3 vs Strata v0.1.44.1).
- Different calendar days (FreeToken baseline 2026-09-19, Strata runs 2026-10-15).
- Two Strata topologies on the same day: 1×4090 and 4090+5060 Ti
(
layer_split=auto).
What stays fixed for the score tables: the same text qualbench-50 suite (no multimodal), and the same practical questions (score, wall time, context ceiling, and which stack you would pick for which job).
Headline numbers:
| Stack | Score | Wall |
|---|---|---|
| FreeToken FP8 (1×4090) | 47/50 | ~2372 s (~40 min) |
| Strata IQ3_S (1×4090) | 49-50/50 | 586-711 s (0.2.11 586 s; prior recheck 644 s); ~3.3-4× vs FT |
| Strata IQ3_S (1×4090, parallel=2) | 50/50 | 596 s; two batch slots; ~0.5 GiB VRAM free |
| Strata IQ3_S (2×GPU split) | 50/50 | 966 s (~16 min); ~2.5× vs FT, ~1.36× slower than 1× Strata |
| Strata UD-Q4_K_XL / UD-IQ4_XS (A/B, rolled back) | 48/50 | slower long prefill / +RAM vs IQ3_S |
| Maya Maya-S24 GLM-5.3-Flash (2026-10-30) | 41/50 | 596 s (long-ctx mostly 400s); decode ~30 t/s; 32K cap |
| Gemma-4 31B QAT / vLLM (2026-11-07, temporary) | 37/40 (~37/50) | ~6.5 min runnable cats; decode ~41 t/s; 3072 cap |
| Gemma-4 12B QAT / vLLM (2026-11-07, live temp) | 42/50 | 461 s; decode ~51 t/s; prefill ~5-6.5k; 131072 |
| Strata IQ3_S + gpu-unlock (2026-10-31, rolled back) | 48/50 (flaky) | 645 s; prefill/decode ≈ locked (~0-1%) |
Real coding work (1×4090, session ~12:54-02:57, 351 Done): 319,588 generated tokens in 7,351 s (~2 h) ≈ 43.5 tok/s wall; decode ~91-180 (median ~124), heavy prefill median ~1.9k. Details in the section below.
The stacks
| FreeToken | Strata 1×4090 | Strata 2×GPU | |
|---|---|---|---|
| Date | 2026-09-19 | 2026-10-15 | 2026-10-15 |
| Engine | FreeToken 0.1.3 | Strata v0.1.44.1 | Strata v0.1.44.1 |
| Model | Qwen3.6-35B-A3B-FP8 | Flash-Next IQ3_S | Flash-Next IQ3_S |
| GPUs | GPU0 4090 | GPU0 4090 | GPU0+1, layer_split=auto |
| Advertised context | 262144 | 262144 | 262144 |
| Vision | ON | ON | ON (smoke PASS) |
| Concurrent requests | max 4 | now parallel: 2 | default 1 |
Both single-card stacks push the 4090 close to full (~23-24 GiB). Strata 1× also held ~62 GiB host RAM (experts + streamed KV). On the 2×GPU run, the 5060 Ti held early layers (~8.5-11 GiB) while the 4090 kept the rest plus head/MTP. Sum VRAM ~35 GiB; that is not a faster solo stream.
For Strata windows, ASR/embedding containers on GPU1 were stopped so the split (or a clean 1× run) was not fighting other workloads.
Qualbench-50 (text): score and wall time
Same category set: java-spring, ts-angular, sql-migrations, mcp-tools, security-review, long-context. Multimodal was left out. FreeToken already has a separate vision eval article; Strata only got a vision smoke here.
| Category | FreeToken | Strata 1× | Strata 2× | Wall FT → 1× → 2× |
|---|---|---|---|---|
| Total | 47/50 | 50/50 | 50/50 | 2372 → 639-711 (recheck 644) → 966 s |
| java-spring | 9/10 | 10/10 | 10/10 | 613 → 83 → 96 s |
| ts-angular | 8/8 | 8/8 | 8/8 | 408 → 62 → 61 s |
| sql-migrations | 4/6 | 6/6 | 6/6 | 362 → 61 → 48 s |
| mcp-tools | 8/8 | 8/8 | 8/8 | 48 → 15 → 24 s |
| security-review | 8/8 | 8/8 | 8/8 | 319 → 93 → 108 s |
| long-context | 10/10 | 10/10 | 10/10 | 623 → 397 → 630 s |
The three FreeToken failures in that baseline (java 07-money, sql 04 and
05) are the documented FP8 truncation / reasoning-loop class. On both
Strata topologies those three also passed, so avoidable-failure count was
0/50.
Tool-calling parity held: 8/8 mcp-tools on all three columns. Score moved up vs FreeToken while wall time moved down; tools did not get faster because quality dropped. One 4090 beat two-GPU Strata mainly on long-context (397 s vs 630 s).
Prefill / decode matrix: 1×4090 vs layer-split
Same IQ3_S matrix harness, same day. Cold = first pass; warm prefix cache stayed ~0.09-0.14 s TTFT on A-D for both.
| Tier (cold) | 1× prefill t/s | 2× prefill t/s | Δ | 1× decode | 2× decode |
|---|---|---|---|---|---|
| A ~1K | 376 | 400 | +6% | 52 | 44 |
| B ~4K | 1437 | 817 | -43% | 55 | 47 |
| C ~42K | 1903 | 1252 | -34% | 58 | 51 |
| D ~85K | 1931 | 1275 | -34% | 61 | 54 |
| E ~170K | ~2060 | ~1293 | -37% | 75-123 | 77-95 |
On long prompts, one 4090 is ~1.3-1.6× faster at prefill. Decode on the split is usually ~10-15% slower for short generations. Layer-split here buys sum VRAM / expert footprint, not single-stream tok/s.
Why the split is slower: PCIe, not "more GPUs = more speed"
On this host the cards talk over PHB (through the CPU, no NVLink). Link widths at runtime were already half of max: 4090 at PCIe 4.0 ×8 (max ×16), 5060 Ti at 4.0 ×4 (max ×8). Strata's layer-split is pipeline parallelism: activations cross stages through pinned host memory each window. That matches the matrix shape. Tiny prompts nearly tie, then B-E lose a third or more once PCIe/host handoffs dominate.
Strata's own docs note the same trade-off: when the first card can hold the
working set, skipping the split (split_skip_if_fits) recovers prefill. For
max solo long-context throughput on this box, leave IQ3_S on the 4090 alone
and keep the 5060 Ti for ASR/embeddings.
Throughput and context (vs FreeToken)
| Metric | FreeToken | Strata 1×4090 | Strata 2×GPU |
|---|---|---|---|
| Decode tok/s | typically 40-80 | ~50-150 | similar band, often a bit lower |
| Prefill tok/s (cold, long) | up to ~1500 | ~1900-2100 | ~1250-1300 |
| Full qualbench-50 | ~2372 s | 685-711 s | 966 s |
| long-context category | 623 s | 397-398 s | 630 s |
| 150K task wall | ~87-98 s | ~77 s | ~122-135 s |
Context ceiling (verified, not brochure):
| FreeToken | Strata 1× | Strata 2× | |
|---|---|---|---|
Advertised (n_ctx) | 262144 | 262144 | 262144 |
| qualbench verified | 150K | 150K | 150K |
| Practical prompt ceiling | - | needle OK at ~248K (3/3) | needle OK at ~248K (3/3) |
| Raw filler = 262144 | - | HTTP 400 | HTTP 400 |
| Risk | concurrent KV pressure | single-flight; little free VRAM | PCIe split latency on long prefill |
Working max on 1×4090 for this stack: aim for about 240-248K prompt
tokens, not the full advertised 262144. Engine n_ctx stays 262144; the
extra ~14K is the headroom you need for chat template + generation. Strata's
1× (and later 2×) context matrix is the evidence: tiers A-E passed, and a
calibrated ~248K needle passed at 10% / 50% / 90% after raising max_tokens so
reasoning did not eat the entire budget. Filling the window with exactly
262144 filler tokens still fails with HTTP 400.
That is a different failure mode from the dense Qwen3.8-27B-NVFP4 article on the same card, where the served KV budget collapsed to ~5.6K because dense weights left almost no VRAM for cache. Flash-Next + Strata keep long context reachable by streaming KV and parking experts in RAM.
Real coding work (not a bench)
Qualbench and the A-E matrix are controlled runs. Below is a continuous daytime coding session: growing context (up to ~109K), short acks mixed with long patches, typical prefix reuse ~4.5K.
Snapshot from the Strata UI (1×4090, prefill in the IQ3_S band), 12:54-02:57, all 351 Done:
319,588 generated tokens in 7,351 s (~2 h 3 min) ≈ 43.5 tok/s wall.
| Metric | Value |
|---|---|
| Requests | 351 Done |
| Prompt | 357-108,945 |
| Output sum | 319,588 |
| Duration sum | 7,351 s (~123 min) |
| Wall tok/s | ≈ 43.5 (= output / duration) |
| Decode t/s | 90.8-179.7 (median 123.6) |
| Heavy prefill t/s (270 requests, reused under half the prompt) | 370-2,148 (median ~1,914) |
| VRAM hit rate | typically ~85-94% (+ fractions % PCIe) |
Wall ~43.5 with decode ~90-180 is expected: on long prompts most of the wall clock is heavy prefill, not generation. The UI decode figure is the rate after prefill; how fast the coding agent feels is closer to wall tok/s. The synthetic decode band 50-150 in the throughput table above is the peak after prefill; a live coding loop on this host sits around ~40-45 tok/s wall.
Agent API compatibility
Correctness suites that speak OpenAI/Anthropic shapes are not the same as qualbench. On a fast agentbench subset, Strata 1× scored 50 passed / 5 failed / 3 skipped; 2× was 49 / 6 / 3. Same class of contract mismatches:
- context advertised as
meta.n_ctxinstead of FreeToken'smax_model_len; /v1/messages/count_tokensreturned 401;- a couple of reasoning-budget / tool-loop cases that FreeToken's suite already treated as model- or contract-sensitive.
Chat completions, streaming, and tool calling were largely green. Qualbench
mcp-tools at 8/8 on both Strata topologies agrees that the tool path works for
the coding tasks that suite cares about. Layer-split does not fix the API
contract. Gateways that hard-code FreeToken field names still need a thin
compat layer (or test updates); for Bifrost llm-88 the OpenAI chat path was
good enough to cut over with the same Virtual Keys (model id renamed to
qwen3.8-flash-next-iq3_s).
What this means in practice
| Scenario | Prefer |
|---|---|
| Text qualbench quality and speed on this host | Strata IQ3_S on 1×4090 (50/50, fastest wall); still the score/speed champ |
| Unsloth Q4 / IQ4 packs (A/B) | Measured 48/50; rolled back (pay RAM + slower long prefill for −2 SQL) |
| Long-context / Flash-Next needle ladder toward ~248K | Strata 1×4090 IQ3_S (leave ~14K under 262144) |
| Try GLM-5.3-Flash on the same 4090 | Maya-S24; usable <32K, ~30 t/s decode; stop Strata for the window |
| Try Gemma-4 31B QAT on the same 4090 | vLLM W4A16; ~41 t/s, strong <3K on suite, but not efficient for real work (need ≥32K, prefer 128K) |
| Try Gemma-4 12B QAT (allowed; live temp) | vLLM @ 131072; qual 42/50 vs 50/50; peak decode ~51 vs ~90-180; coding wall proxy ~46 vs Strata UI ~43.5; not a Strata replacement |
| Occupying both GPUs under one LLM | 2× split works (50/50) but slows long prefill here |
| Keep GPU1 for ASR / embeddings | Do not hand it to layer-split if chat latency matters |
Production Bifrost llm-88 / OpenCode on this host | Strata IQ3_S when restored (qwen3.8-flash-next-iq3_s, engine v0.2.11 / 0.1.57, parallel: 2, limit 248000; gpu-unlock off). Temporary window: Gemma on :8080 |
| Faster tensors via gpu-unlock on this IQ3_S path | No. Ada unlock works, Strata gain ≈ 0%; leave cmdline without targets= |
| Two light concurrent chats on this 4090 | Strata parallel: 2 works (qual 50/50); watch VRAM ~0.5 GiB free |
| Concurrent requests (up to 4) | FreeToken still wins for higher fan-out; Strata here is 2 slots |
| Multimodal MMMU / Video-MME numbers | FreeToken (already measured); Strata smoke only here |
| Rollback | Unmask Strata bak / disable Gemma; FreeToken / Q4 / Maya / inert gpu-unlock packages on disk |
This is a stack pick for a specific host and suite. Changing the engine and the checkpoint at the same time means you cannot credit the score lift or the wall-time cut to IQ3_S alone or Strata alone. You can credit the pair on this card, on this suite, on these dates, and separately note that pipeline split across a narrow PCIe PHB link did not win for single-user speed.
Lessons
- Say what is held constant. Same GPU and same suite are enough for an operational comparison; they are not enough for a scientific A/B on one variable.
- Wall time is part of the quality story. A 50/50 that finishes in twelve minutes changes how often you will actually re-run the suite after a server upgrade.
- More GPUs ≠ more tok/s for Strata layer-split on consumer PCIe. Measure
prefill; check
nvidia-smi topoand link width before assuming a win. - Advertised 262K is still not free. Strata's practical prompt ceiling on
1×4090 is ~248K with calibration; clients (OpenCode, agents) should
advertise that budget, not the raw
n_ctx. FreeToken's earlier articles already warned thatmax_model_lenis not the served budget. Read the run that fits, not the metadata line. - API contract and task score diverge. agentbench fails on field names can coexist with a perfect mcp-tools category. Pick the metric that matches the job (gateway compatibility vs coding-task pass rate).
- Dense 27B and Flash-Next IQ3_S are different 3.8 stories. The NVFP4 dense article is about a short-context fit; this one is about a long-context MoE quant on a different engine. Do not merge the conclusions.
- A bigger MoE on Maya is another axis. GLM-5.3-Flash via Maya-S24 fits the same 4090 and codes well under 32K, but loses the long-context ladder and most of Strata's decode feel. Score the ceiling, not only the pass rate.
- Dense Gemma QAT is yet another ceiling. 31B W4A16 fits only at 3072 (unusable for agents). Allowed 12B reaches 128K, scores 42/50, peak decode ~51 (~2-3× behind Strata's ~90-180), but a gen-heavy coding-wall proxy lands ~46 tok/s next to this article's Strata UI ~43.5. Competition / experiment stack; restore Strata for prod.
- Unlocking GeForce tensor rate is not free IQ3_S speed. On Ada 4090 the unlock path worked; Strata's quantized MoE prefill/decode did not move. Measure your actual stack before keeping a tainted kernel module in prod.
"parallel": 2is real concurrency, not a solo turbo. On this IQ3_S 4090 it admits two batch slots and keeps qualbench green, but free VRAM drops to ~0.5 GiB. Set it for two clients, not to speed one OpenCode session.
Resources
- Strata (Qwen3.8-Flash-Next inference): https://github.com/Niko1221/Strata
- FreeToken: https://github.com/FlashML-org/FreeToken
- Project Maya: https://github.com/mw00/project-maya
- gpu-unlock: https://github.com/Zagitta/gpu-unlock
- Qwen3.8-Flash-Next: https://huggingface.co/Qwen/Qwen3.8-Flash-Next
- llm-tests (qualbench / agentbench): https://github.com/berdachuk/llm-tests
- Gemma-4 12B QAT on an RTX 4090: Qualbench at 128K
- Running Qwen3.6-35B-A3B at 262K Context with FreeToken MoE Offload
Published on 11/7/2026