Maya GLM-5.3-Flash on an RTX 4090: Qualbench, Speed, and a 32K Ceiling
This host already runs Strata IQ3_S (Qwen3.8-Flash-Next) on the RTX 4090
for Bifrost llm-88. The open question was whether GLM-5.3-Flash, a much
larger MoE, can share that card via Project Maya
and how it scores on the same text suites.
Not a side-by-side live deploy. Maya needs the whole 4090 and pins most free host RAM. Strata was stopped for the window, then restored. ASR / embeddings on the 5060 Ti stayed up.
Headline:
| Stack | Qualbench-50 | Wall | Decode (short) | Context |
|---|---|---|---|---|
| Strata IQ3_S (prod, recheck same evening) | 50/50 | 644 s | Monitor warm 119 t/s; probe ~100-180 | 262K adv. / ~248K practical |
| Maya Maya-S24 (this run) | 41/50 | 596 s | ~27-45 t/s | 32K hard |
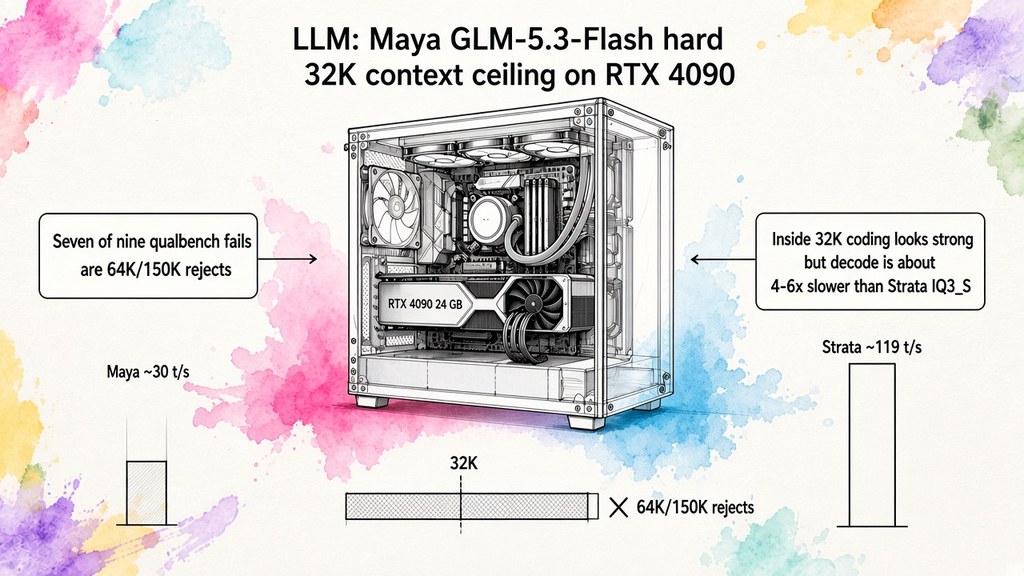
Seven of Maya’s nine fails are 64K / 150K long-context tasks that the server rejects with HTTP 400. Inside 32K, coding and security look strong.
The stack
| Value | |
|---|---|
| Date | 2026-10-30 |
| Engine | Project Maya v1.1.41 |
| Quant | Maya-S24 (~94.7 GB, pre-downloaded) |
| Served id | glm-5.3-flash |
| GPUs | GPU0 RTX 4090 only (--no-vision) |
| Port | :8090 (Strata keeps :8080 for rollback) |
| Advertised context | 32768 |
| Host RAM while serving | pins most free RAM (~85+ GiB used class) |
| VRAM GPU0 | ~23.7 GiB |
LAN INPUT for 8090 was not opened on this host (only 8080 has a nopasswd
helper). Client suites reached Maya through an SSH local forward
(localhost → 127.0.0.1:8090).
Smoke and official Maya bench
| Gate | Result |
|---|---|
/v1/models | OK: glm-5.3-flash, n_ctx=32768 |
Chat PONG | content OK; decode 27.5 t/s |
./maya.sh --bench | decode mean 30.5 t/s; prefill 2K 389, 8K 1295 |
Vs Strata Monitor-class decode on the same card (~110-180 t/s on short turns), Maya is roughly 4-6× slower at generation. Prefill can still be competitive on mid-size prompts once warmed.
Monitor (suite)
| Cell | prompt_tok | prefill t/s | decode t/s |
|---|---|---|---|
| warm8k | 10424 | 1648 | 42.4 |
| reuse2k | 2624 | 630 | 27.3 |
Agentbench
Same FreeToken-oriented suite used against Strata. Maya is not FreeToken:
| Mode | Pass / fail / skip | Wall |
|---|---|---|
| fast | 49 / 6 / 11 | ~202 s |
| slow | 49 / 11 / 6 | ~213 s |
Expected fail class:
- models payload uses
meta.n_ctx/context_length, notmax_model_len; /v1/messages/count_tokens→ 404;- some malformed-request cases return 200 where the suite wants ≥400;
- FreeToken-specific
think_off/tool_choice=requiredassertions; - slow suite needles at 60K / 200K →
context_length_exceeded.
Chat completions, streaming, and tool calling were largely green, matching qualbench mcp-tools 8/8.
Context matrix (≤32K)
Strata’s raw tier C targets ~32K filler but measures ~42K prompt tokens on this harness, over Maya’s hard cap.
| Tier | Result | Notes |
|---|---|---|
| A ~1K | PASS | cold decode ~36-50 t/s |
| B ~4K | PASS | cold prefill ~1007 t/s |
| C target 32768 | FAIL HTTP 400 | ~42.5K prompt |
| C-calib ~24K target → ~31.1K pt | PASS cold | prefill 2329 t/s, decode 44.8 |
| C-calib warm (session reuse) | PASS | TTFT ~0.06 s |
So Maya does hold ~31K prompts on this card; the suite’s naive 32K filler sizing still overflows.
Qualbench-50
Same categories as the Strata article (no multimodal):
| Category | Maya | Strata IQ3_S (recheck 2026-10-30) |
|---|---|---|
| Total | 41/50 @ 596 s | 50/50 @ 644 s |
| java-spring | 10/10 | 10/10 |
| ts-angular | 7/8 | 8/8 |
| sql-migrations | 5/6 | 6/6 |
| mcp-tools | 8/8 | 8/8 |
| security-review | 8/8 | 8/8 |
| long-context | 3/10 | 10/10 |
Quality fails inside budget: ts-angular/03-shopping-cart,
sql-migrations/02-unique-constraint-dupes. Long-context: all 8K needles
passed; every 64K / 150K task failed at request time (400), not at
retrieval.
Wall time looks “faster” than Strata’s ~11 min only because the long-context category mostly aborted in <1 s each. That is not a throughput win.
What this means
| Scenario | Prefer |
|---|---|
Prod Bifrost llm-88 / OpenCode on this host | Strata IQ3_S when restored (engine v0.2.11, parallel: 2; gpu-unlock off). Temporary 2026-11-07 window: Gemma-4 QAT on :8080 |
| Long prompts / ~150K-248K work | Strata (Maya’s 32K ceiling ends the race) |
| Try GLM-5.3-Flash locally on one 4090 | Maya-S24 (fits, decode ~30 t/s, strong <32K coding/security) |
| Try Gemma-4 31B QAT on the same card | vLLM W4A16 (~41 t/s, 3072 cap; see /ai/gemma-4-31b-qat-rtx-4090-qualbench) |
| Concurrent chat + ASR on GPU1 | Stop Strata for Maya; do not layer-split Maya with the 5060 Ti in v1 |
| Agent harness written for FreeToken field names | Expect contract fails; OpenAI chat + tools still usable |
Lessons
- Same suite, different ceiling. A 41/50 with seven context rejects is mostly a product limit, not a “GLM cannot code” story.
- Decode SLA matters. ~30 t/s is usable for interactive coding; it is not Strata Flash-Next’s feel on this box.
- RAM is part of the cost. Maya pins almost all free host RAM for expert tiers; plan downtime and do not leave it overnight without watching thrash.
- Rollback first. Keep Strata on
:8080, Maya on:8090, never disable units, only stop, so restore is onesystemctl --user start.
Resources
- Project Maya: https://github.com/mw00/project-maya
- Strata: https://github.com/Niko1221/Strata
- llm-tests (qualbench / agentbench): https://github.com/berdachuk/llm-tests
- Gemma-4 31B QAT on an RTX 4090: Qualbench, Speed, and a 3K Ceiling
- Running Large Language Models Locally: Complete Hardware Guide for GLM-4.7 Deployment
Published on 10/30/2026