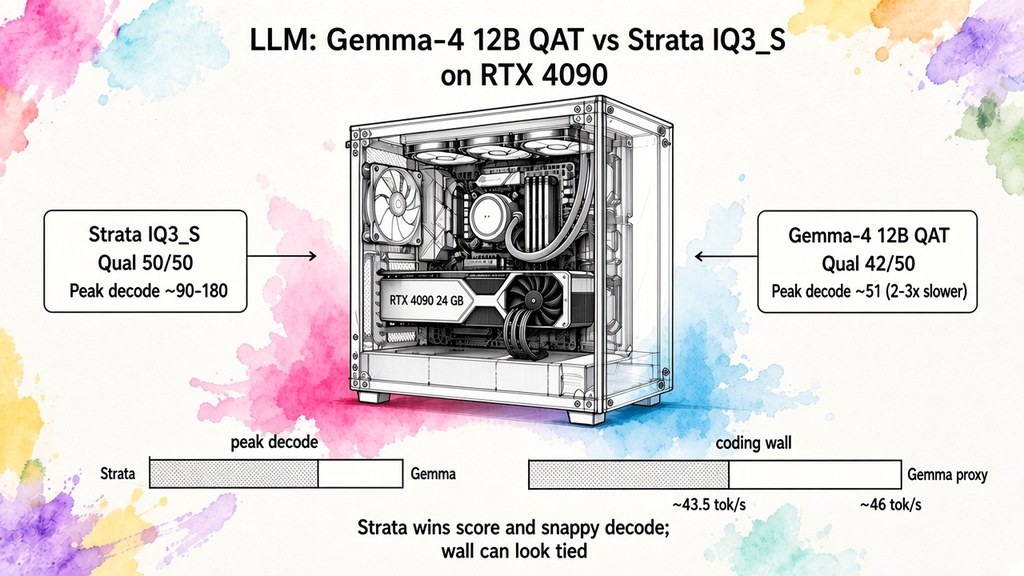
Gemma-4 12B QAT on an RTX 4090: Qualbench at 128K
Same host as the Strata IQ3_S / Bifrost llm-88 stack. After the 31B QAT
cutover proved that ~23 GB weights leave only max-model-len≈3072 (below the
≥32K floor, prefer 128K, for real agent work), we switched to the allowed
competition checkpoint google/gemma-4-12B-it-qat-w4a16-ct (~10.3 GB W4A16).
Still a temporary cutover. Strata’s unit stays masked; GPU1 ASR, embeddings, and Frida stay up. 12B is one of the four official QAT variants for the main Gemma 4 Developer Agent track (pick exactly one; all agents must share it).
Headline:
| Stack | Qualbench | Wall | Decode (short) | Context |
|---|---|---|---|---|
| Strata IQ3_S (prod, parallel=2) | 50/50 | ~596 s | ~90-180 t/s | 262K / ~248K |
| Maya Maya-S24 | 41/50 | 596 s | ~27-45 t/s | 32K |
| Gemma-4 31B QAT (earlier same day) | 37/40 (~37/50) | ~6.5 min runnable | ~41 t/s | 3072 |
| Gemma-4 12B QAT (this run) | 42/50 | 461 s | peak ~51 t/s; coding wall ~46 | 131072 |
Long-context is back: 7/10 on the same needle suite that was 0/0 skipped under 31B.
Measured speed (this host, 2026-11-07)
Wall-clock probes against live :8080 after warm-up (vLLM 0.25.1, util 0.95,
max-num-seqs=1, eager):
| Probe | Prompt tok | Completion tok | Wall | Rate |
|---|---|---|---|---|
| Short decode (count 1…40) | 31 | 111 | 2.18 s | decode ~51 tok/s |
| Mid prefill + tiny reply | 1820 | 2 | 0.35 s | prefill ~5.2k tok/s |
| ~7k prefill + tiny reply | 7020 | 2 | 1.08 s | prefill ~6.5k tok/s |
| Streaming short | - | - | TTFT ~55 ms | - |
Vs Strata Flash-Next on the same card (~90-180 decode), 12B is roughly 2-3× slower at peak generation, but much faster than Maya (~30 t/s) and a bit quicker than the earlier 31B QAT fit (~41 t/s). Prefill on mid prompts is strong; the product limit was context, not raw tok/s.
Coding-session wall (same formula as Strata)
Strata’s published ~43.5 tok/s wall was a real OpenCode UI session (output_sum / Σ request duration). For Gemma we ran a synthetic proxy with the same formula: growing context, substantial patches, few tiny acks.
| Session | Requests | Prompt range | Output sum | Σ duration | Wall tok/s |
|---|---|---|---|---|---|
| Strata IQ3_S (real UI, ref) | 351 | 357-108,945 | 319,588 | 7,351 s | ≈ 43.5 |
| Gemma 12B gen-heavy proxy | 20 | 1,297-68,819 | 10,072 | 217 s | ≈ 46.4 |
| … subset prompt ≥20K | 12 | 21.8K-68.8K | - | - | ≈ 43.8 |
| … short prompt <8K | 5 | - | - | - | ≈ 52.5 |
| Gemma 12B ack-heavy proxy (v1) | 24 | 774-61,704 | 1,637 | 168 s | ≈ 9.8 |
On a generation-heavy mix Gemma’s wall lands near Strata’s ~43.5. That is not because decode matches (it does not: ~51 vs ~90-180), but because Strata’s real session was also prefill-taxed. A session full of short acks after long prompts collapses Gemma wall to ~10 tok/s. Treat ~44-46 as the coding-like wall on this card when the agent actually emits patches; treat peak decode ~51 as the post-prefill ceiling.
The stack
| Value | |
|---|---|
| Date | 2026-11-07 |
| Engine | vLLM 0.25.1 (gemma4-12b-qat.service) |
| Weights | google/gemma-4-12B-it-qat-w4a16-ct (~9.56 GiB safetensors) |
| Served ids | gemma-4-12b-it-qat + alias qwen3.8-flash-next-iq3_s |
| GPUs | GPU0 RTX 4090 only |
| Port | :8080 |
| Context | max-model-len=131072, util 0.95, max-num-seqs=1 |
| Tools | --enable-auto-tool-choice --tool-call-parser gemma4 |
| VRAM GPU0 | ~23.2 GiB used |
31B unit disabled; nvidia-guard prefers 12B when enabled.
Why 12B, not 31B
| 31B QAT | 12B QAT | |
|---|---|---|
| Competition | allowed | allowed |
| Weights on disk | ~23.3 GB | ~10.3 GB |
| Practical ctx on 4090 | 3072 | 131072 |
| Real agent / OpenCode | not efficient | meets ≥32K / ~128K target |
| Qualbench (same day) | ~37/50 (no long-ctx) | 42/50 |
Suites
agentbench fast: 46 / 8 / 11 / 1 (~68 s). Concurrency 3/3. Main fails
remain API-contract / reasoning_effort (empty content).
Qualbench-50:
| Category | 12B | 31B (earlier) | Strata IQ3_S |
|---|---|---|---|
| Total | 42/50 @ 461 s | ~37/50 | 50/50 @ ~596 s |
| java-spring | 8/10 | 10/10 | 10/10 |
| ts-angular | 7/8 | 7/8 | 8/8 |
| sql-migrations | 4/6 | 4/6 | 6/6 |
| mcp-tools | 8/8 | 8/8 | 8/8 |
| security-review | 8/8 | 8/8 | 8/8 |
| long-context | 7/10 | 0/0 skipped | 10/10 |
Vs Strata IQ3_S (same host, same suites)
Quality: Strata wins. Gemma matches on mcp-tools / security (8/8), but drops
coding/SQL and long-context: 42/50 vs 50/50 (−8). The agentbench chat/tools
path is usable; remaining fails are mostly API-contract / reasoning_effort,
not “cannot code”.
Speed: Peak decode still favors Strata (~90-180 vs ~51, about 2-3×). Coding wall (output / Σ duration, gen-heavy proxy up to ~69K prompt): Gemma ~46 tok/s vs Strata’s real-UI ~43.5. Similar wall when both are prefill-taxed; Strata still wins the snappy post-prefill feel. Ack-heavy long-context loops on Gemma drop wall to ~10 tok/s.
Context: Both clear the practical bar (≥32K, prefer 128K). Gemma serves 131072; Strata still goes to ~248K practical / 262K advertised.
| Axis | Winner | Note |
|---|---|---|
| Qualbench score | Strata | 50/50 vs 42/50 |
| Peak decode | Strata | ~90-180 vs ~51 (~2-3×) |
| Coding wall (gen-heavy) | ~tie | Gemma proxy ~46 vs Strata UI ~43.5 |
| Mid-prompt prefill | ~tie / Gemma OK | 12B ~5-6.5k wall-ish |
| Context ceiling | Strata | ~248K vs 128K |
| Kaggle-legal on 4090 | Gemma 12B | allowed QAT; usable 128K |
What this means
| Scenario | Prefer |
|---|---|
Prod Bifrost llm-88 / long OpenCode | Strata IQ3_S when restored |
| Kaggle main-track agent on local 4090 | 12B QAT @ 128K: legal, usable; not Strata-quality |
| Day-to-day coding feel on this card | Strata: score + decode |
| Paper: size vs ceiling on one 4090 | 31B@3K vs 12B@128K vs Strata |
Clients sending reasoning_effort | Strip it or read reasoning channel |
Lessons
- Pick the allowed size that leaves KV. Competition allows four QAT checkpoints; only 12B (and smaller) leave a 24 GB card with a real context budget.
- ≥32K / prefer 128K is the product bar. Crossing that line mattered more than the raw pass-rate jump from ~37 to 42.
- Usable is not better than Strata. 12B clears the context floor and keeps tools/security green, but loses on score and decode feel. Keep it for competition and experiments; restore Strata for prod.
- Same port, new product. Bifrost alias still works; advertise 131072 to clients, not the old 3072 OpenCode limits.
Resources
- Model: https://huggingface.co/google/gemma-4-12B-it-qat-w4a16-ct
- Strata IQ3_S vs FreeToken on an RTX 4090: Qualbench Score and Speed
- Maya GLM-5.3-Flash on an RTX 4090: Qualbench, Speed, and a 32K Ceiling
- llm-tests: https://github.com/berdachuk/llm-tests
Published on 11/7/2026