Gemma-4 31B QAT on an RTX 4090: Qualbench, Speed, and a 3K Ceiling
Update (2026-11-07, evening): replaced on :8080 by Gemma-4 12B QAT
(max-model-len=131072, qualbench 42/50). 31B stays on disk as the
“weights-fit / no-KV” baseline. Detail:
/ai/gemma-4-12b-qat-rtx-4090-qualbench.
This host normally runs Strata IQ3_S (Qwen3.8-Flash-Next) on the RTX 4090 for
Bifrost llm-88. For the Kaggle Gemma-4 paper track we temporarily moved
:8080 to google/gemma-4-31B-it-qat-w4a16-ct (~23.3 GB W4A16) under
vLLM 0.25.1 and ran the same text suites.
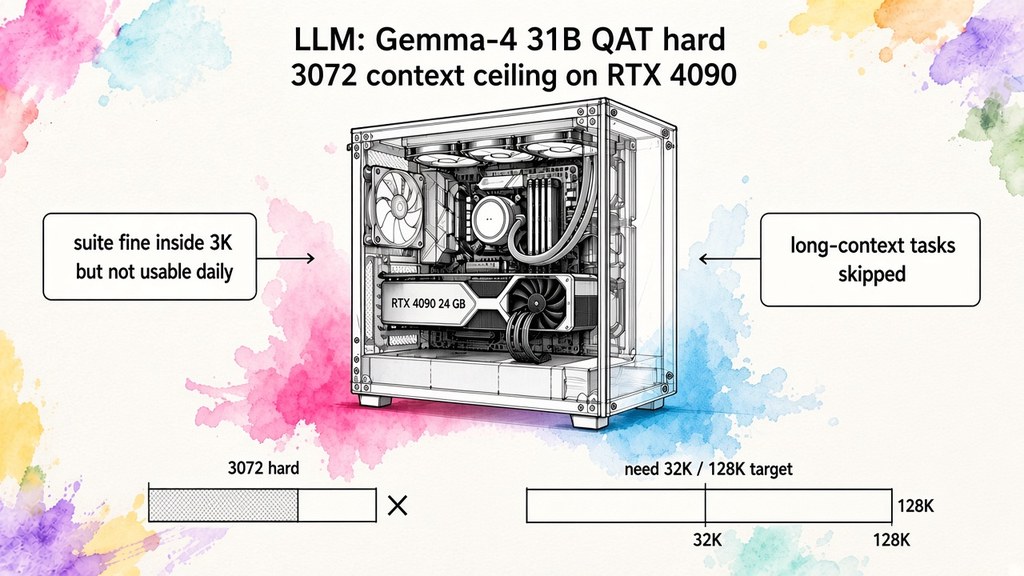
Not a side-by-side live deploy. The weights nearly fill the 24 GB card, so KV
forces a hard max-model-len=3072. Strata’s user unit was masked for the
window (bak on disk). ASR, embeddings, and Frida on the 5060 Ti (GPU1) stayed
up and healthy after reboot.
Headline:
| Stack | Qualbench | Wall / notes | Decode (short) | Context |
|---|---|---|---|---|
| Strata IQ3_S (prod, parallel=2) | 50/50 | ~596 s | Monitor-class ~90-180 t/s | 262K adv. / ~248K practical |
| Maya Maya-S24 GLM-5.3-Flash | 41/50 | 596 s | ~27-45 t/s | 32K hard |
| Gemma-4 31B QAT (this run) | 37/40 runnable (~37/50) | coding+security+mcp ~6.5 min | ~41 t/s; prefill ~2k | 3072 hard |
Ten classic long-context tasks never ran (the harness skips when advertised context < 8K). Inside the 3K budget, Java, MCP, and security were perfect, but ~3K is not a usable coding budget. Real agent / OpenCode work needs at least 32K context; 128K is the comfortable target for multi-file sessions. At 3072, a few tool rounds or a modest file paste already blow the window, so this cutover is a fit/smoke experiment, not an efficient daily driver on this card.
Why 3K fails for real work
| Budget | Reality on this host |
|---|---|
| 3072 (this Gemma fit) | Suite cats that fit still pass; interactive coding stalls after a short transcript |
| ≥32K | Minimum for agent loops with tools + a couple of source files |
| ~128K | Preferred for multi-file / long OpenCode sessions (Strata IQ3_S territory) |
Dense 31B W4A16 on a 24 GB 4090 spends almost all VRAM on weights. There is no room left for a 32K to 128K KV cache. Raising context without a smaller checkpoint, offload, or a bigger GPU is not an option here.
The stack
| Value | |
|---|---|
| Date | 2026-11-07 |
| Engine | vLLM 0.25.1 (gemma4-31b-qat.service) |
| Weights | google/gemma-4-31B-it-qat-w4a16-ct (~23.3 GB) |
| Served ids | gemma-4-31b-it-qat + alias qwen3.8-flash-next-iq3_s |
| GPUs | GPU0 RTX 4090 only (CUDA_VISIBLE_DEVICES=0) |
| Port | :8080 (same public path as Strata) |
| Context | max-model-len=3072, gpu-memory-utilization=0.98, max-num-seqs=1, enforce-eager |
| Tools | --enable-auto-tool-choice --tool-call-parser gemma4 |
| Auth | same Strata API key (nginx Bearer injection unchanged) |
Public path unchanged: Bifrost → llm-88.berdachuk.com → nginx .51 →
.175:8080. Bifrost allowlist still uses the Qwen alias; the Gemma id may
403 until allowlisted.
Smoke and speed
| Gate | Result |
|---|---|
/v1/models | OK: gemma-4-31b-it-qat, max_model_len=3072 |
Chat pong | OK |
| Short decode (suite probes) | ~41 tok/s |
| Prefill (mid prompts) | ~2k tok/s |
Vs Strata Flash-Next on the same card (~100-180 decode), Gemma is roughly 2-4× slower at generation and sits in a different context class.
Agentbench
| Mode | Pass / fail / skip / xfail | Wall |
|---|---|---|
| fast | 44 / 10 / 11 / 1 | ~72 s |
concurrency (MAX_RUNNING=1) | 3/3 | - |
Main fail class: missing /v1/messages/count_tokens, empty content when
clients send reasoning_effort (tokens go to the reasoning channel), and a
few agentic / multi-turn tool edges. The OpenAI chat + Gemma tool-parser path
was good enough for qualbench mcp-tools 8/8.
Qualbench
Same categories as the Strata article (no multimodal). Long-context skipped by harness.
| Category | Gemma-4 QAT | Strata IQ3_S (prod) |
|---|---|---|
| Runnable total | 37/40 (~37/50 if long-ctx count as fail) | 50/50 @ ~596 s |
| java-spring | 10/10 | 10/10 |
| ts-angular | 7/8 | 8/8 |
| sql-migrations | 4/6 | 6/6 |
| mcp-tools | 8/8 | 8/8 |
| security-review | 8/8 | 8/8 |
| long-context | 0/0 skipped | 10/10 |
Quality fails inside budget: ts-angular/03-shopping-cart, two SQL cases.
Harness note: default qualbench max_tokens 4k-6k exceeds 3072 → HTTP 400;
reasoning_effort: low yields empty content. Suite used temporary
overrides (max_tokens=1536, no reasoning_effort).
Isolation
GPU1 stacks stayed up through cutover, reboot, and suite:
| Endpoint | Status |
|---|---|
:8002 speaches | 200 |
:8004 embedding | 200 |
:8006 frida | 200 |
What this means
| Scenario | Prefer |
|---|---|
Prod Bifrost llm-88 / long-context OpenCode | Strata IQ3_S (restore: unmask unit, disable Gemma) |
| Kaggle / Gemma-4 paper experiments on this host | vLLM QAT on :8080: fits 4090, ~41 t/s, but 3K is not efficient for real work (want ≥32K, ideally 128K) |
| Coding / MCP / security inside a few thousand tokens | Gemma scores well on the suite; still too small for day-to-day agents |
| Concurrent ASR + embeddings on GPU1 | Leave GPU1 alone; cutover only masks Strata on GPU0 |
Clients that send reasoning_effort | Strip it for Gemma or read the reasoning channel |
Lessons
- Weight fit is not usable context. 23.3 GB W4A16 leaves almost no KV on a 24 GB card; 3072 is the practical ceiling here (4096 OOM’d). That sits below the 32K minimum (and far below the 128K preference) for agent / OpenCode work. Score the ceiling before the pass rate.
- Same public port, different product. The alias keeps Bifrost green; score and context change under the same model id.
- Harness defaults can lie.
max_tokensandreasoning_effortthat work on Strata break Gemma until the client is tuned. - Rollback is a unit swap. Keep Strata bak + unmask path; do not delete the IQ3_S pack for a temporary cutover.
Resources
- Model: https://huggingface.co/google/gemma-4-31B-it-qat-w4a16-ct
- vLLM: https://github.com/vllm-project/vllm
- Strata: https://github.com/Niko1221/Strata
- llm-tests (qualbench / agentbench): https://github.com/berdachuk/llm-tests
- Maya GLM-5.3-Flash on an RTX 4090: Qualbench, Speed, and a 32K Ceiling
Published on 11/7/2026